Five years ago, telling a sales manager that their CRM was actively losing them deals would have got you laughed out of the room. Today it is established fact. Bad data leads to bad targeting, bad targeting leads to bad conversion rates, and bad conversion rates get blamed on the sales team instead of the system. Studies across mid-market B2B companies consistently show that between 20-30% of CRM records contain critical errors, wrong email domains, outdated job titles, duplicate entries, or missing ownership fields that cause leads to fall through assignment cracks entirely.
In short. Bad CRM data quietly costs deals through wrong targeting and missed follow-ups, and a one-time cleanup does not last. Data quality automation works in three layers: validate data at entry, enrich and deduplicate records continuously, and run scheduled audits that flag decaying records to their owners.
Figures in this guide are illustrative estimates built from typical costs and published sources, not results from PURIST clients. Individual results vary by starting baseline, team size, existing tooling, and how closely a business follows the specific workflow design described; treat the numbers here as a realistic range, not a guarantee.
CRM data quality is not one thing, it is an ecosystem of interconnected degradation. Contacts go stale at roughly 25-30% per year as people change jobs, companies are acquired, and email addresses change. Duplicates accumulate every time a form submission creates a new contact without checking for an existing match. Missing fields compound over time as the CRM grows and not all team members follow the same data entry discipline. What starts as a minor hygiene issue becomes, within 18 months, a system that the sales team stops trusting, and a system they stop trusting is a system they stop updating, creating a negative feedback loop that accelerates the decay.
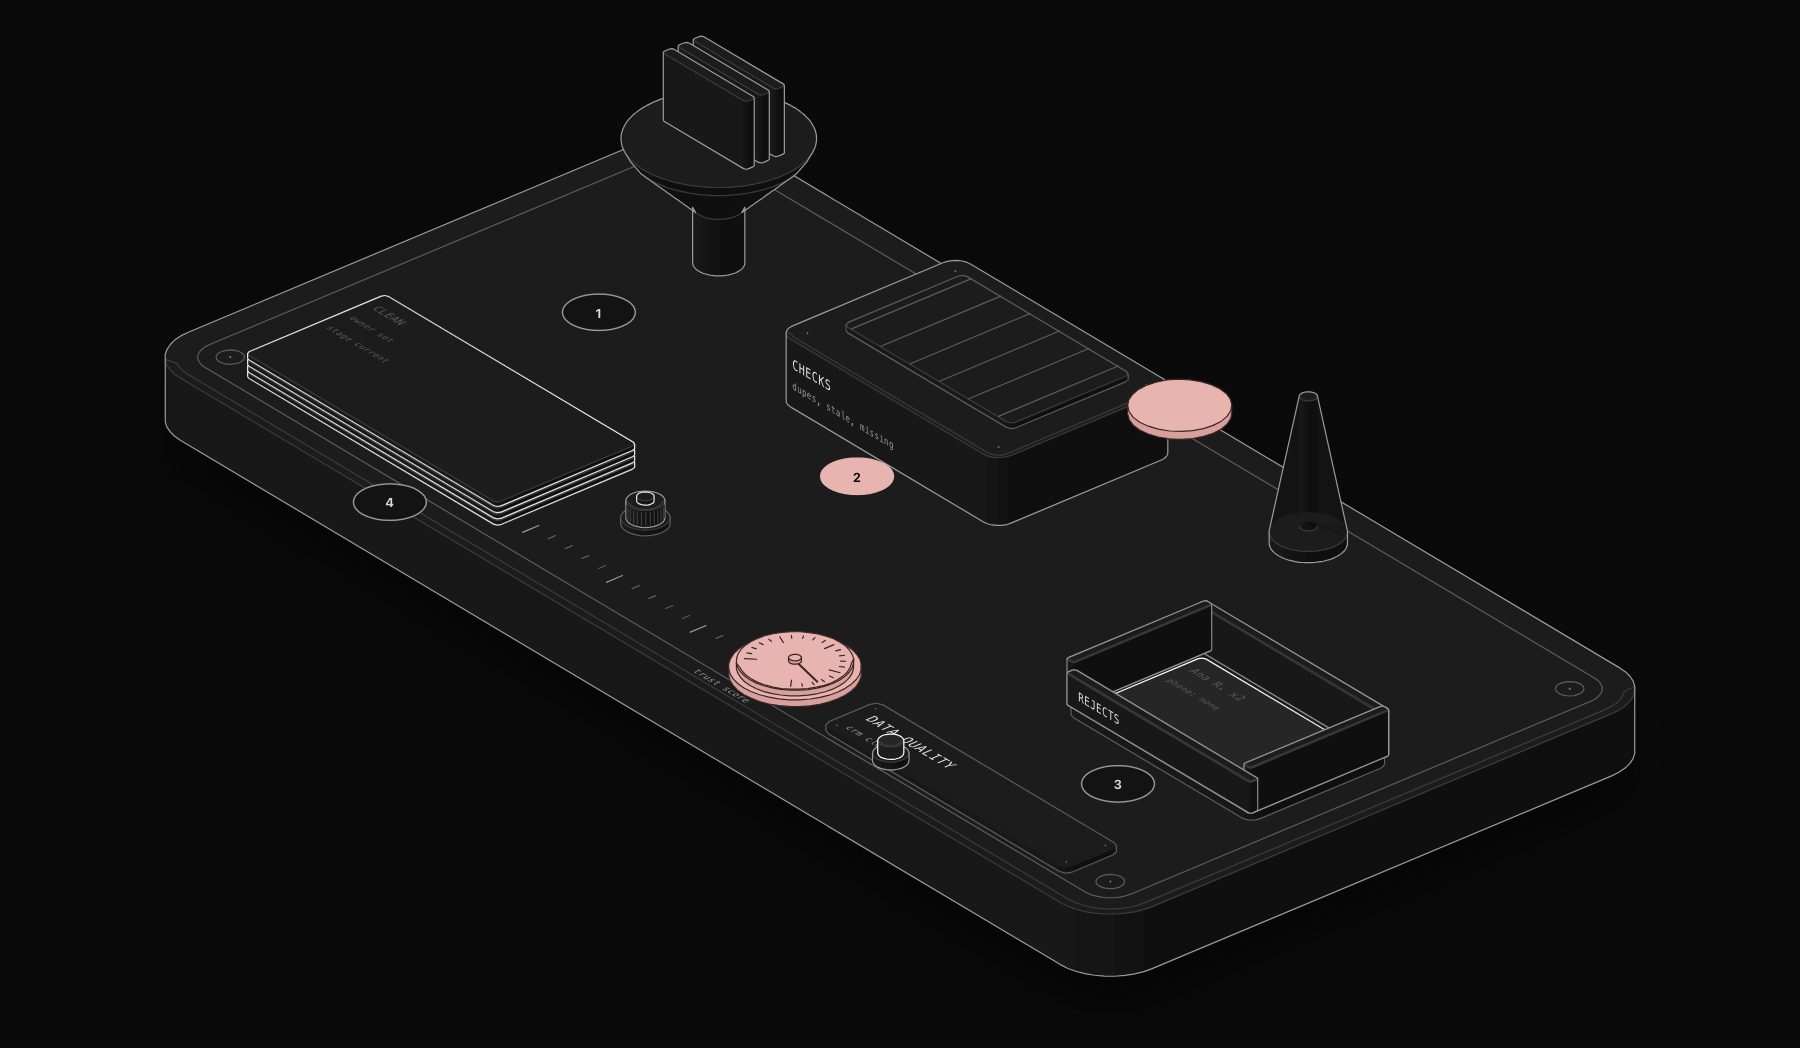
The PURIST approach to CRM data quality is three-layer automated hygiene. The first layer is real-time validation at the point of entry. Every new contact created, whether from a form submission, a manual entry, or a third-party integration, passes through a validation workflow that checks for existing matches using fuzzy name matching and email domain comparison, enriches missing fields via a business data API, standardizes phone number format and timezone fields, and assigns the contact to the correct owner based on territory rules. This prevents new bad data from entering the system.
The second layer is scheduled bulk remediation. A weekly n8n workflow scans the existing CRM database for records matching known decay patterns, email addresses that have started bouncing, contacts with no activity in 180 days, companies with LinkedIn URLs that no longer resolve. These records are flagged with a 'Review' tag and assigned to the relevant account owner with a task to verify or archive within 14 days. The third layer is real-time enrichment triggered by deal stage changes. When a deal moves to 'Proposal Sent,' a workflow automatically re-enriches the contact and company record with current data, ensuring the sales team is working with fresh information at the highest-stakes moments in the pipeline. With all three layers in place, pipeline data accuracy typically improves markedly within the first few months.
The Cost of Bad Data, Quantified
| Decay pattern | Typical annual rate | Downstream cost |
|---|---|---|
| Contact staleness (job changes, company moves) | 25-30% per year | Missed renewal and expansion opportunities, bounced outreach |
| Duplicate records | Accumulates with every unchecked form submission | Split activity history, inconsistent territory assignment, double-counted pipeline |
| Missing or incorrect ownership fields | Grows as team structure changes without CRM updates | Leads sitting unassigned or assigned to a departed rep |
| Incomplete enrichment fields | Compounds as manual entry discipline varies by rep | Poor segmentation, inaccurate lead scoring |
Applied to a mid-market B2B pipeline, a commonly cited 20-30% critical-error rate in CRM records translates directly into misrouted or under-served leads at exactly the volume that matters most, the leads actively in an active buying window.
Why "Just Clean It Once" Doesn't Work
A one-time data cleanup project, deduplicating records, standardizing fields, archiving stale contacts, feels like a solution but addresses a symptom, not the underlying decay mechanism. Without the three-layer automated hygiene system described in this article's core, entry-point validation, scheduled bulk remediation, and deal-stage-triggered enrichment, the CRM begins decaying again immediately after the cleanup, at the same 20-30% annual rate that created the problem in the first place. This is precisely why PURIST scopes CRM data quality as an ongoing automated system rather than a one-time project engagement.
Measuring the Improvement Honestly
Tracking "pipeline data accuracy" requires a defined measurement, not a vague sense that things feel cleaner. PURIST's standard metric samples a rolling set of records monthly and checks them against a defined accuracy rubric: valid, deliverable email domain; current job title and company (cross-checked against a business data API); no unresolved duplicate flag; correct territory-based ownership. Moving this metric from a sub-70% baseline to above 92% within 90 days, the figure cited in this article, requires all three hygiene layers running simultaneously; any single layer alone typically plateaus well below that improvement.
Sources & Further Reading
CRM data decay-rate figures reflect commonly cited B2B data-quality industry benchmarks; treat the specific percentages as directional ranges that vary by industry and company size, and measure your own baseline before assuming a specific figure applies to your CRM. For the CRM platform decision underneath this hygiene layer, see our HubSpot vs Salesforce vs Pipedrive vs Zoho CRM comparison, and for the broader pipeline automation this connects to, see our CRM automation complete guide.
Frequently Asked Questions
How do I measure my current CRM data accuracy before starting?
Sample a random 100-150 records and manually check each against the accuracy rubric above (valid email, current title/company, no duplicate, correct ownership). This gives a baseline percentage to compare improvement against, rather than relying on a general sense that "the data is messy."
Which enrichment data providers work best for this kind of automation?
Any business data API with reasonable coverage and a webhook or API-callable interface works technically; the more important factor is matching the provider's data freshness and country coverage to your actual customer base, similar to the accuracy-versus-cost tradeoffs covered in our Apollo vs ZoomInfo vs Lusha vs Cognism comparison.
Won't automated deduplication accidentally merge two different people with similar names?
A well-built fuzzy-matching workflow uses multiple signals (email domain, company, phone, not just name) and routes ambiguous matches to a human review queue rather than auto-merging anything below a high confidence threshold, precisely to avoid this failure mode.
How often should the bulk remediation workflow run?
Weekly is a reasonable default for most mid-market CRMs; higher-volume operations with faster data decay (high sales-rep turnover, fast-growing contact lists) may benefit from a more frequent cadence, while smaller, more stable CRMs can run it less often without meaningful accuracy loss.
Does this hygiene system work with any CRM, or only HubSpot and Salesforce?
The three-layer pattern is CRM-agnostic; it depends on the CRM having a usable API for real-time validation and scheduled queries, which the major platforms (HubSpot, Salesforce, Pipedrive, Zoho, and others) all support, though the specific implementation details vary by platform.
Tags
Purist Team
The PURIST editorial team covers automation, AI agents, and operations strategy for businesses scaling with n8n, Make, and Claude AI.